

Most organisations do not need more data. They need their existing data to work better.
At Ardent, we spend a significant amount of time inside large-scale client data platforms that are already mature, operational, and delivering value. These are not greenfield environments. They are complex ecosystems built over years, often supporting critical reporting, analytics, and operational workflows.
Increasingly, we are being asked a new question: are they ready to support AI?
For many of our clients, the honest answer is no.
Not because the data is insufficient, but because the way it is structured, processed, and maintained was never designed for systems that learn, adapt, and respond in near real time.
This is not simply an extension of existing data strategy. It represents a shift in how data platforms are expected to behave.
The Ardent Perspective
Our experience working with organisations such as Ericsson, AT&T, and Ipsos has consistently shown that the primary constraint is not introducing intelligence into controlled settings but enabling more adaptive behaviour within systems that were originally designed for stability and predictability.
In these environments, data platforms are often:
Operating close to their limits
Tightly coupled across multiple processes
Layered with transformation logic that has evolved over time
These characteristics are not flaws. They reflect systems that have been extended to meet real business needs.
However, they do introduce constraints.
When new capabilities are introduced without addressing these constraints, complexity does not reduce, it increases. This is why many organisations see early success in isolated AI use cases but encounter friction as they attempt to scale.
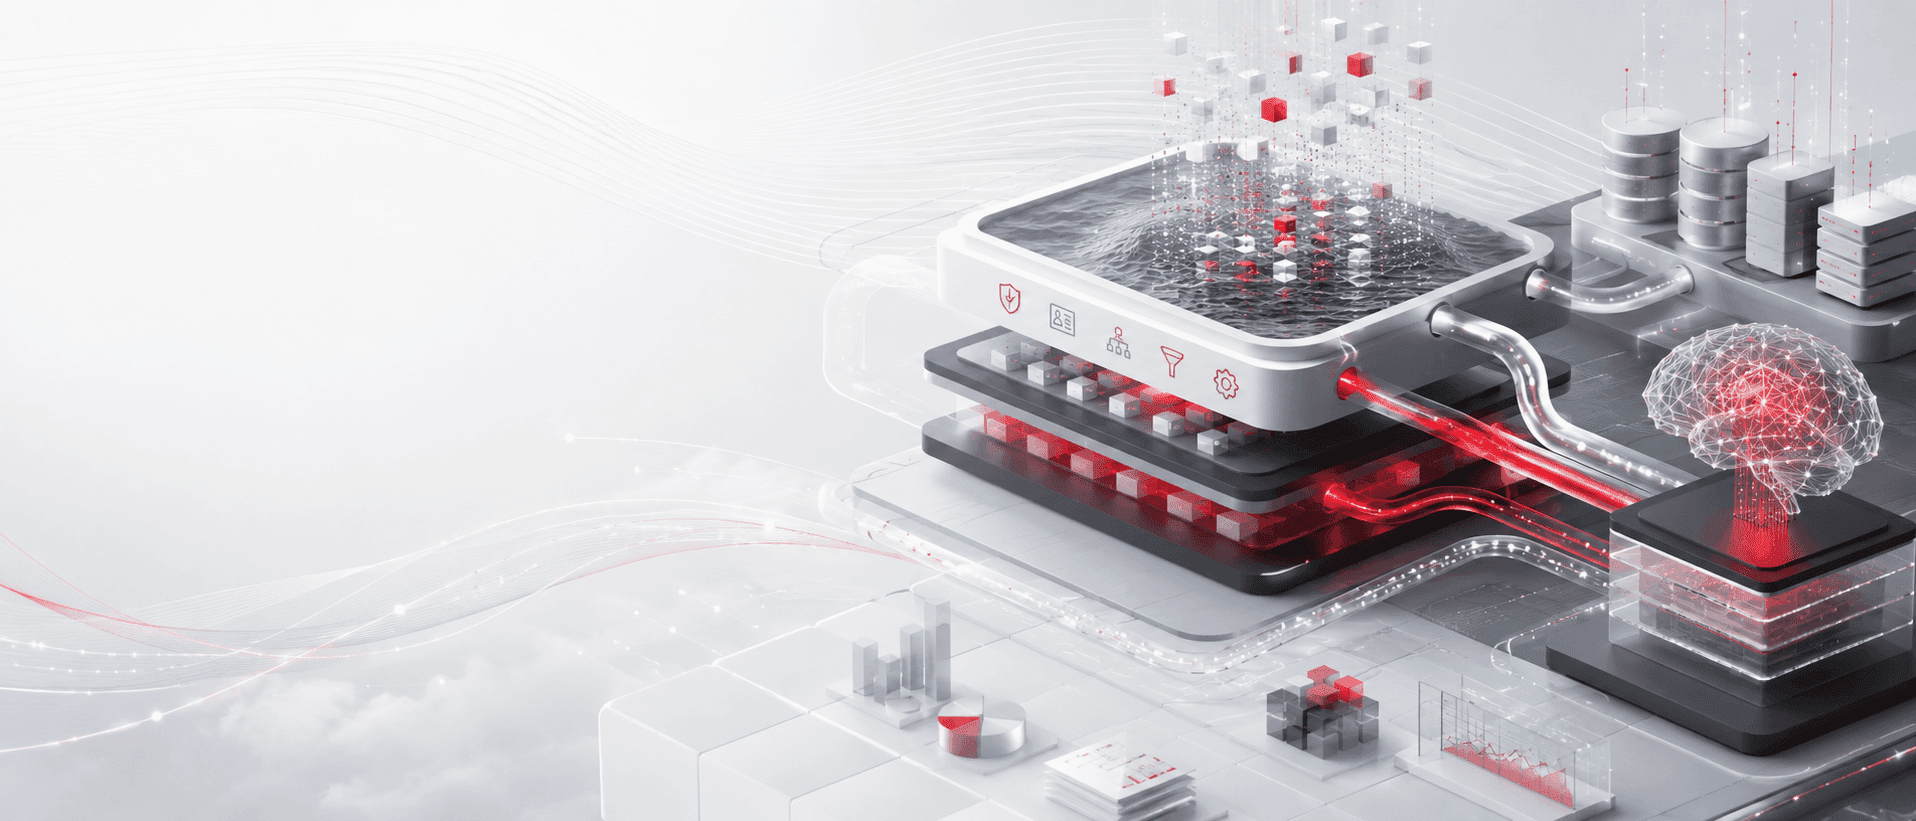
In practice, the limiting factor is rarely tooling or model capability. It is whether the underlying data platform can support more adaptive, feedback-driven behaviour. Something traditional pipeline design was never intended to handle.
Why Existing Pipelines Struggle Under AI Demands
This shift toward more adaptive systems is happening under increasing pressure to reduce cost, improve efficiency, and respond more quickly to change.
At the same time, many existing data platforms already carry significant operational overhead.
Pipelines that rely on duplicated logic, manual intervention, or tightly coordinated processes become increasingly difficult to maintain as demands increase.
These pressures expose structural limitations that are already present:
Fragmented transformation logic: Business rules duplicated across ETL, warehouses, and reporting layers create inconsistency and reduce reliability.
Latency embedded in architecture: Batch processing and scheduled refresh cycles delay data availability in time-sensitive scenarios.
Static logic in dynamic environments: Predefined rules struggle to accommodate changes in schema, data structure, or business requirements.
Limited observability and lineage: As systems grow more complex, understanding and trusting data behaviour becomes more difficult.
These are not tooling issues. They are the result of how systems have been designed and extended over time.
Improving how pipelines operate is therefore not only a prerequisite for supporting AI, but also a way to remove inefficiencies that already exist. In many cases, AI-readiness emerges as a consequence of making these systems more effective.
Translating Direction into Action
Addressing these challenges does not always require replacing whole existing systems. The most effective approach is typically incremental and targeted.
A useful starting point is to identify where the system is already under strain:
Where pipelines fail
Where latency affects decisions
Where complexity slows change
The next step is translating that direction into changes that can be applied within your business.
In practice, a small number of targeted actions tend to deliver consistent value:
1. Consolidate and centralise transformation logic
Action: Remove duplicated business logic and establish a single source of transformation closer to the core platform
Reason: Multiple definitions of the same logic create inconsistency and undermine downstream reliability
Outcome: A coherent and trusted data foundation that supports consistent analytics and model behaviour
2. Reduce latency where it directly impacts decisions
Action: Identify critical pipelines and shift them toward more responsive processing models where necessary
Reason: Not all data needs to be real-time, but delays in key flows reduce relevance at the point of use
Outcome: Data that better reflects current conditions, enabling more effective operational and model-driven decisions
3. Introduce adaptive mechanisms into pipeline design
Action: Reduce reliance on rigid, hardcoded rules and allow pipelines to respond to changes in data structure and usage
Reason: Static logic cannot accommodate evolving schemas or shifting demand without repeated re-engineering
Outcome: Pipelines that absorb change more effectively, reducing maintenance effort and improving resilience
4. Make system behaviour visible and explainable
Action: Implement lineage, traceability, and monitoring that reflects how data behaves, not just when it fails
Reason: As systems become more dynamic, lack of visibility erodes trust and makes issues harder to diagnose
Outcome: Greater confidence in data outputs and a stronger foundation for managing change over time
5. Align processing with actual usage patterns
Action: Prioritise pipelines and datasets based on how they are consumed, rather than treating all data equally
Reason: Uniform processing often leads to wasted effort in low-impact areas while critical workloads remain constrained
Outcome: Resources focused on high-value use cases, improving both efficiency and impact
6. Focus change where it delivers immediate value
Action: Start with pipelines under the greatest strain or those that require frequent intervention
Reason: Broad transformation increases risk; targeted improvement builds momentum
Outcome: Measurable progress without unnecessary disruption, enabling incremental evolution of the platform
These actions are not intended to be applied universally or simultaneously. Their value comes from being introduced selectively, in areas where the system is already under pressure.
Over time, this allows the platform to evolve in a controlled and sustainable way.
A Note on Trade-Offs
Whilst we have detailed the upsides, it is important to recognise that Increasing adaptability within data pipelines also introduces additional concerns.
When a system becomes more dynamic, it requires:
Stronger governance
Clearer versioning
Better understanding of how changes propagate
The objective is not to maximise flexibility across the entire platform, but to apply it selectively where it provides the most value.
In practice, this often means maintaining stability in core reporting pipelines while enabling more responsive behaviour in areas that support time-sensitive or evolving use cases.
What This Means Now
A divide is emerging between organisations whose data platforms can adapt and those whose cannot.
Among Ardent clients those that are evolving their pipelines are able to:
Introduce new capabilities with less friction
Respond to change more effectively
Extract greater value from their data
Those that are not, are becoming constrained by the systems that once enabled them.
AI-readiness, in this context, is not a discrete objective. It is a characteristic of how the data platform operates.
AI is already being applied across organisations, often exposing the limitations of the systems it depends on.
The question is no longer whether to invest in AI, but whether the data platform can support it.
We believe that for most of our clients, the answer does not lie in building something entirely new. It lies in evolving what already exists, with a clear focus on how those systems are expected to behave.
The pipelines are already in place. The data is already available. The opportunity is to make them capable of supporting a different class of problem.
Are your businesses data pipelines equipped for the AI changeover? If you would like to discuss how Ardent could help you tackle some of the issues mentioned above, please get in touch: https://www.ardentisys.com/contact-us/

NEWS
Latest Insights
Text to go in here what you want it to say etc…
Ready to make your data work harder?
We build and manage the data foundations that remove the quality, consistency and reliability issues holding back AI, automation and better decisions.